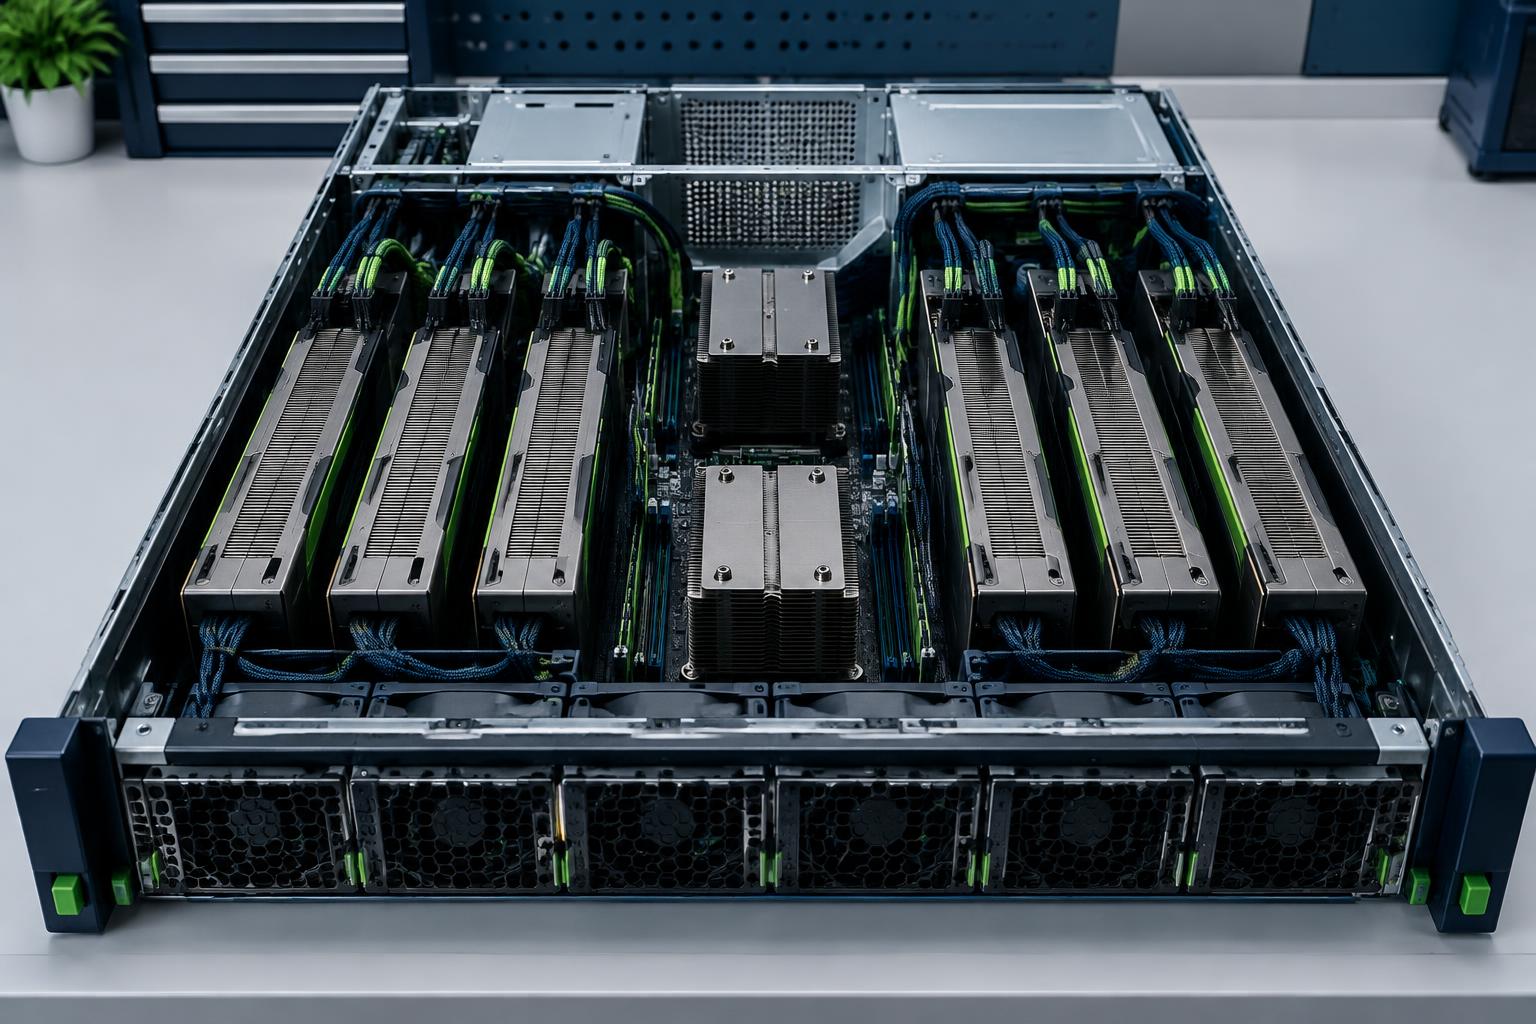
NVIDIA HGX B300 (8-GPU)
Frontier-scale training and high-throughput reasoning inference.
- 8x NVIDIA B300 GPUs
- 288 GB HBM3e per GPU (2.3 TB total)
- 5th-gen NVLink with NVSwitch
- 800G networking ready
OEMs: Supermicro, Dell, HPE, Lenovo, Gigabyte
GPU systems & procurement
From an 8-GPU server to a liquid-cooled rack. Compare compute, memory and interconnect options, then request your exact configuration.
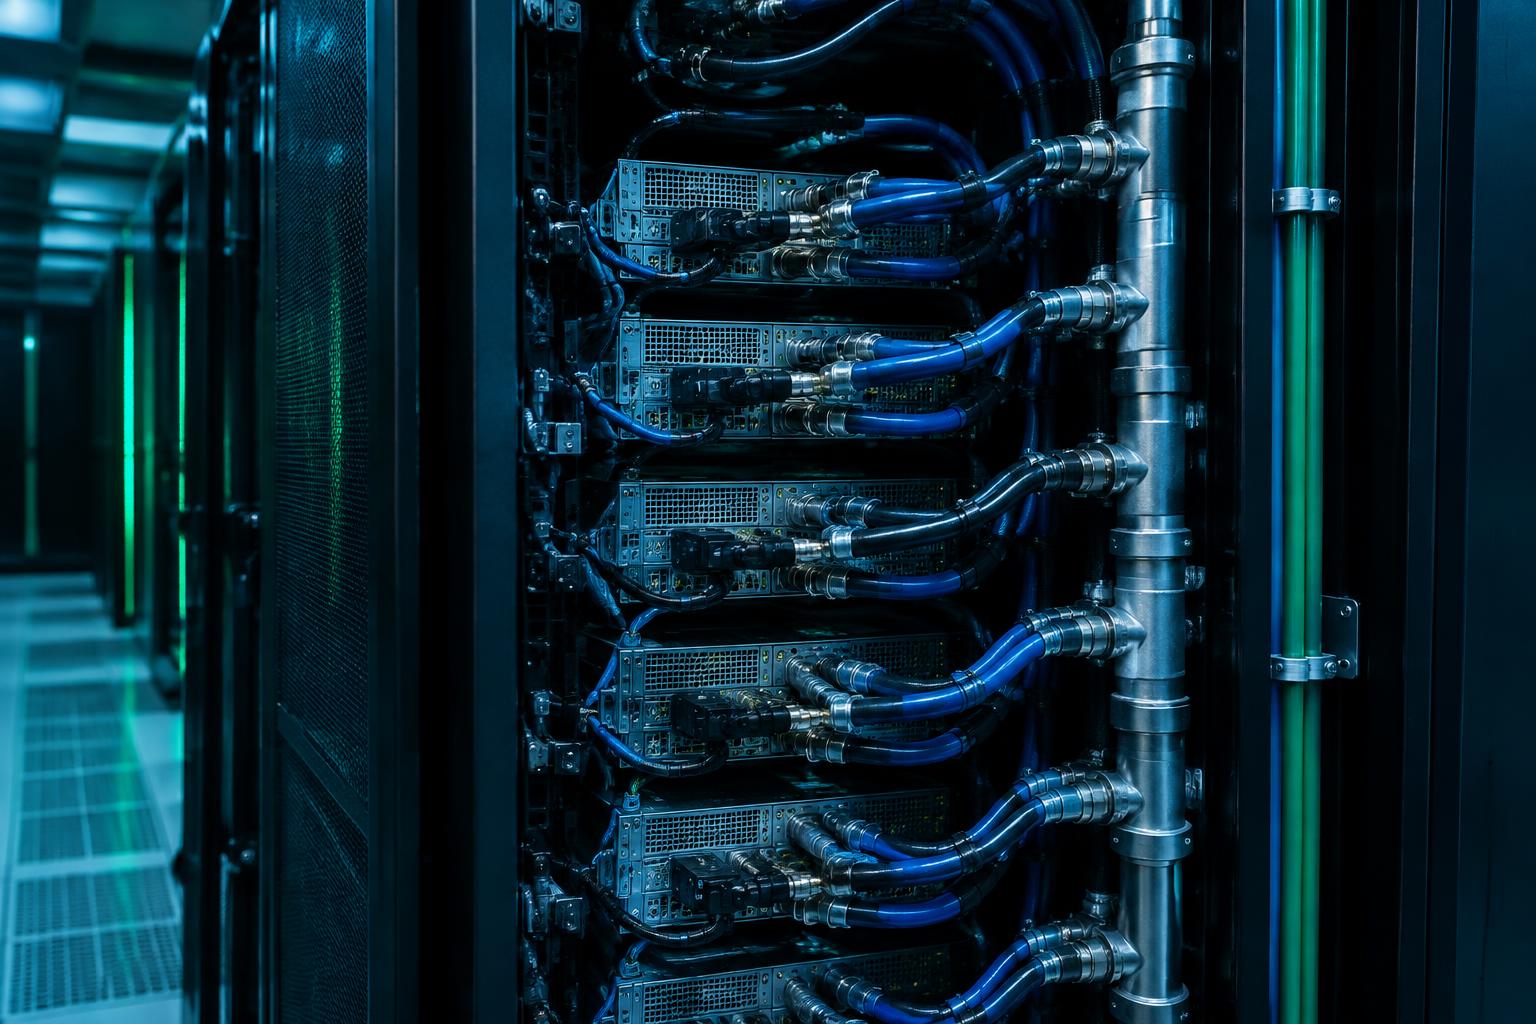
Illustrative infrastructure imagery
6 configurations

Frontier-scale training and high-throughput reasoning inference.
OEMs: Supermicro, Dell, HPE, Lenovo, Gigabyte

Large-model training and inference at strong price-performance.
OEMs: Supermicro, Dell, HPE, Lenovo, Gigabyte

Memory-heavy inference and proven, widely supported deployments.
OEMs: Supermicro, Dell, HPE, Lenovo, Gigabyte

Established training and inference workloads with the widest software maturity.
OEMs: Supermicro, Dell, HPE, Lenovo, Gigabyte

The largest training and reasoning-inference deployments, delivered as a complete liquid-cooled rack that works as a single exascale system.
OEMs: Supermicro (other OEM rack-scale systems on request)

Completing a cluster so GPUs are never waiting on data.
OEMs: NVIDIA and leading storage vendors, on request
| System | GPUs | Memory per GPU | Total GPU memory | Interconnect | Best for |
|---|---|---|---|---|---|
| GB300 NVL72 (rack) | 72x B300 + 36x Grace | 288 GB HBM3e | ~21 TB | NVLink 1.8 TB/s across 72 GPUs | Largest training and reasoning inference |
| HGX B300 | 8x B300 | 288 GB HBM3e | 2.3 TB | NVLink 5 + NVSwitch | Frontier training, reasoning inference |
| HGX B200 | 8x B200 | 180 GB HBM3e | 1.4 TB | NVLink 5 + NVSwitch | Large-model training and inference |
| HGX H200 | 8x H200 | 141 GB HBM3e | 1.1 TB | NVLink + NVSwitch | Memory-heavy inference |
| HGX H100 | 8x H100 | 80 GB HBM3 | 640 GB | NVLink + NVSwitch | Proven training and inference |
Specifications vary by OEM and configuration. Final specifications are confirmed in your quotation.
Tell us your model sizes, users and timeline. We'll recommend the right GPU, OEM and cluster size – and tell you honestly when renting or a smaller system makes more sense.
Get a recommendationTraining large models → HGX B300 or B200
Inference at scale → HGX B200 or H200
Getting started / budget-conscious → HGX H100 or H200
Share workload, quantity and delivery location.
We recommend and compare OEM options.
Formal quote with price, Incoterm, lead time and payment milestones.
30% advance with purchase order; balance before shipping.
Ex Works Jebel Ali or delivered; optional installation and cluster setup.
NVIDIA, HGX, Blackwell, Hopper and other product names are trademarks of their respective owners. Sustainablemindz.ai is an independent supplier.
Share your workload, location and timeline. Start with a configuration quote or an engineering conversation.