Blackwell Ultra
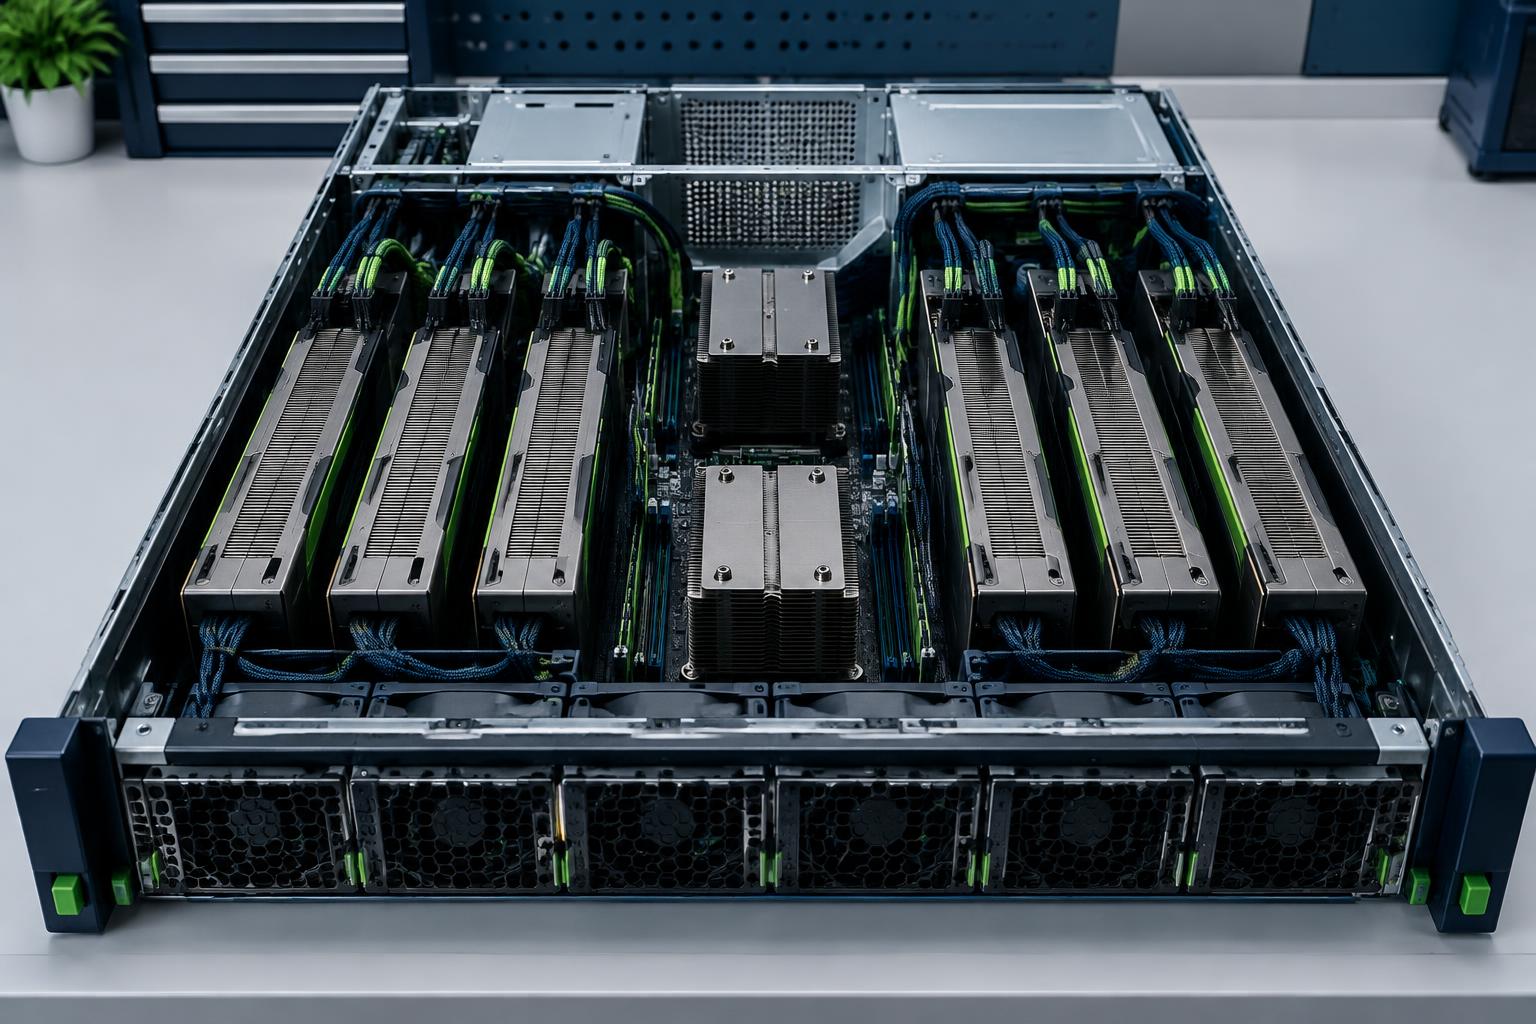
NVIDIA HGX B300
- GPU configuration
- 8x NVIDIA B300 GPUs
- GPU memory
- 288 GB HBM3e per GPU (2.3 TB total)
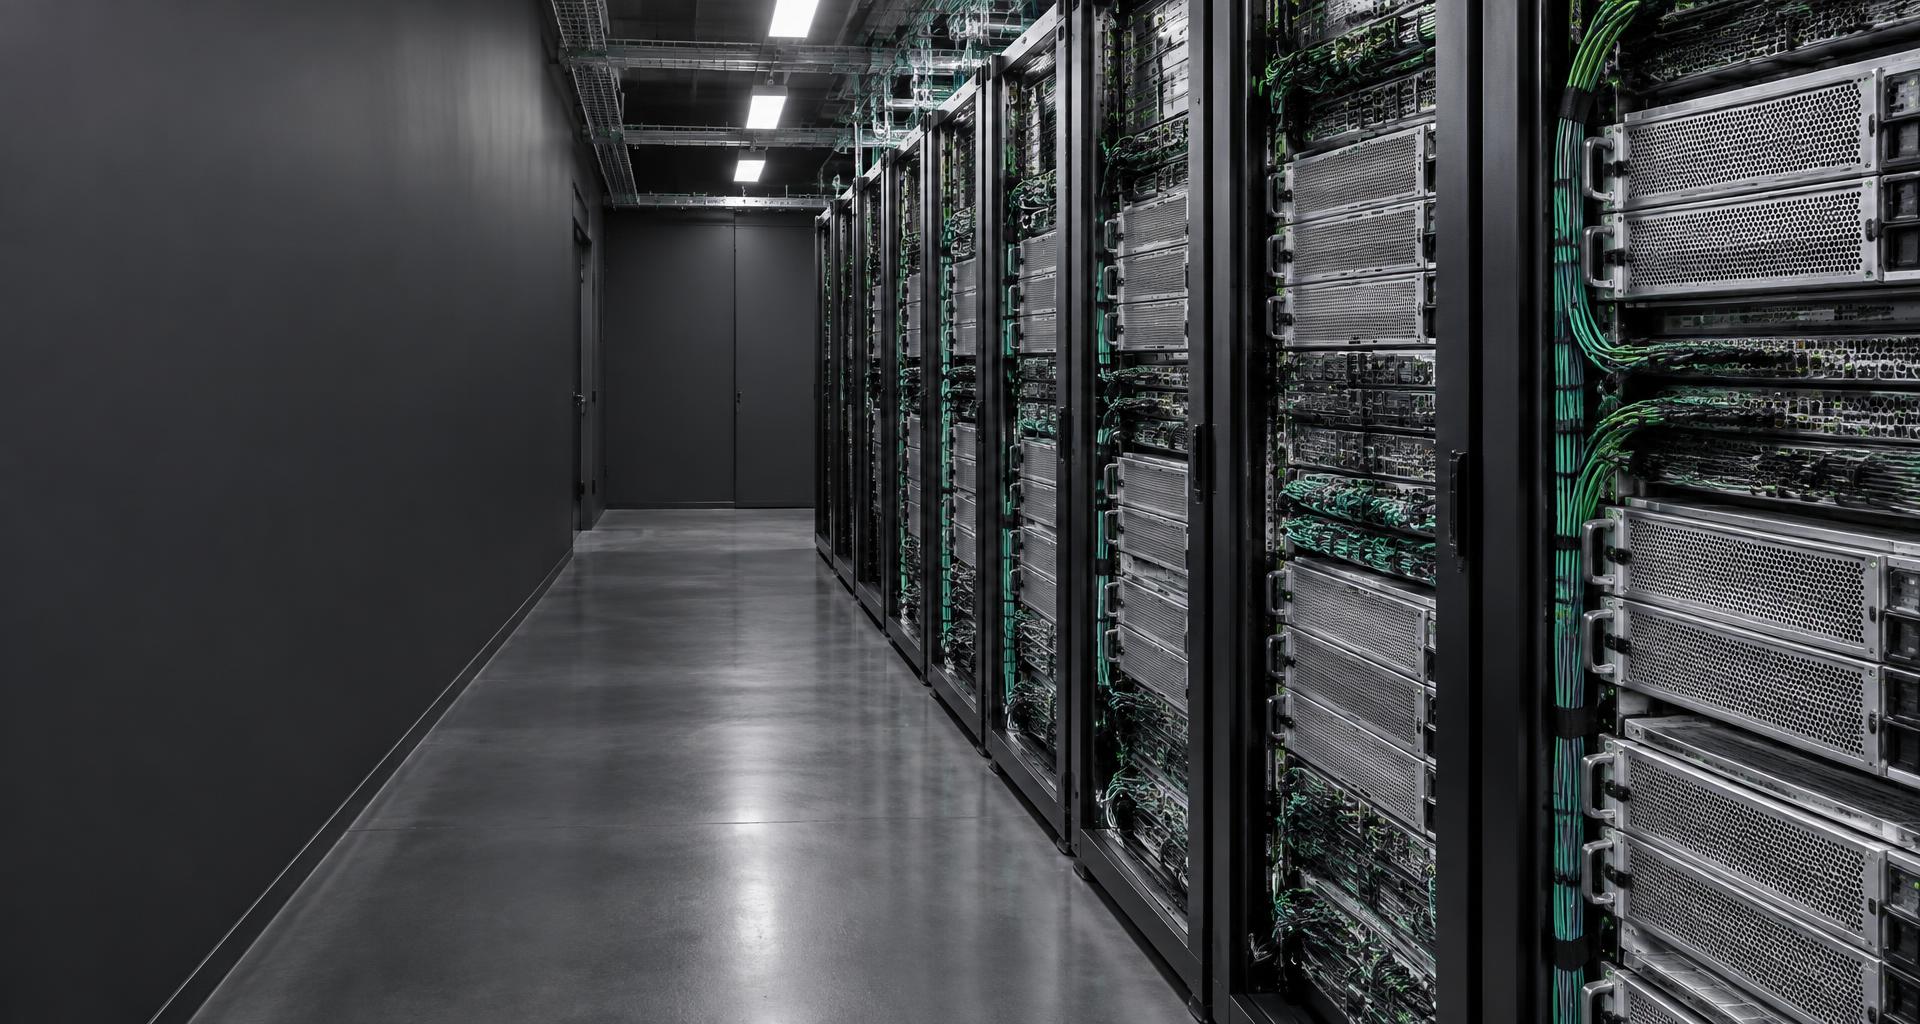
Dubai · AI infrastructure & GPU systems
NVIDIA GPU servers, complete AI infrastructure and cloud environments. Specified for your workload. Delivered with a clear plan.
UAE · GCC · India · UK · Europe / Illustrative infrastructure imagery
From one server to rack-scale
Compute, networking and storage
Procurement to deployment
One clearly defined project scope
Brands we supply




Our capabilities
Start with the capability you need. Bring procurement, architecture and deployment together as your project grows.
We plan and deliver the full stack for AI workloads, from GPU compute and networking to the software layer.
We help you specify, source and buy NVIDIA GPU servers from the leading OEMs, with clear lead times.
Private, hybrid or public: we design and set up the cloud environment for your AI workloads.
Capacity planning, vendor selection and data centre readiness from people who have deployed GPU hardware.
We build AI applications, internal platforms and integrations on top of your compute.
Planning a new environment?
Discuss your projectGPU systems
Blackwell Ultra
Blackwell
Hopper
Hopper
Why Sustainablemindz
Compute, memory, fabric and storage selected around the models you actually run.
Compare configurations, availability and delivery responsibilities before committing.
Power, cooling, software and handover considered alongside the hardware.
Right-size your investment and compare owned, cloud and hybrid options.
A clear delivery path
Define your workload, model sizes, delivery location and operating constraints.
Compare GPU systems and design the supporting network, storage and site requirements.
Review availability, delivery responsibilities and payment milestones before ordering.
Coordinate order progress, shipping documentation and the agreed handover location.
Where included in scope, install, configure and validate the environment with your team.
Built for demanding workloads
Share your workload, location and timeline. Start with a configuration quote or an engineering conversation.